
Why I/O matters
Last updated on 2026-10-27 | Edit this page
Overview
Questions
- What is the difference between a metadata server and a data server?
- Why do a thousand small files cost more than one file of the same total size?
- Which of three files belongs on home?
Objectives
- Separate a file’s name and permissions from the bytes of the file.
- Explain why many small files put extra work on the metadata server.
- Choose home for a small source file, and not for a 10 GB working file.
A job does three kinds of work
An HPC application computes, it sends messages between processes, and it reads and writes files. This lesson is the third of those. The other two can be fast and the job can still sit idle, waiting on the file system.
Input is not one thing. A grid, a genome, or a climate field can be a huge file that many processes read. A job parameter file is small. Output is not one thing either. A checkpoint is large and has to be precise, because the next job starts from it. An analysis file can be a subset. A progress log is a short text file from one process.
Those files do not all belong on the same disk. The next episode names the disks. This episode is why the choice changes the runtime.
The metadata server and the data servers
A parallel file system splits the work across two roles.
The metadata server records the name, the owner, the permissions, the size, and the location of the bytes. Creating a file, opening it, listing a directory, and asking for its size all talk to the metadata server. The record for one file is an inode. A quota can count inodes as well as bytes.
The data servers hold the bytes. Once the metadata server has said where a large file lives, the read and the write talk to the data servers.
ls of a directory with a huge number of names is almost
all metadata. Reading one 10 GB file is one metadata lookup and then a
long transfer from the data servers. The second case is what the fast
disks are built for. The first case can leave those disks idle while the
metadata server has a queue of its own.
On Snellius the scratch areas share a GPFS file system. A path that
realpath prints under /gpfs/scratch1/ is that
file system. Home is a different file system: smaller, and backed up.
You will use both. You should not use them for the same kind of
file.
Why many small files hurt
One thousand files of 1 MB hold the same 1 GB as one file of 1 GB. They are not the same amount of work.
Each small file is a create, an open, a write, a close, and a name to store. That is a thousand trips to the metadata server for a modest amount of data. A copy of the directory repeats the work on the destination: a thousand creates, not one.
One archive of those files is one metadata record and one stream of bytes. The copy is then one lookup and one transfer. The data servers do the work. The metadata server does little. Random bytes do not shrink when you compress them. What you save is the number of files, not the number of bytes. A later episode times the copy. The reason is this one.
The same cost shows up in a quota. Home on Snellius has a cap on
inodes as well as a cap on bytes. A tree of tiny files can hit the inode
cap while du still shows free space.
What home is for
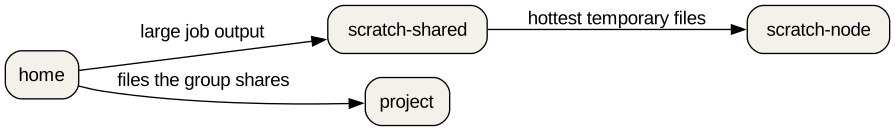
Home is the small, backed-up place. A source file you will edit next week belongs there. If you delete it by mistake, the backup can still have it. On Snellius that backup keeps a deleted home file for three weeks.
A 10 GB file that a job is still writing does not belong there. It is large, it is temporary, and putting it through the backup helps no one. A result you must keep until the project ends is a third case. Scratch will expire. Home will fill. The next episode gives that result a project path and, on Snellius, an archive.
Which file belongs on home?
You have three files:
- A source file of a few kilobytes that you will edit next week.
- A 10 GB file a job is writing and will not need after the run.
- A result you must keep until the project ends.
Which one belongs on home? Where do the other two go?
Only the source file belongs on home. It is small, you will change it, and the backup is there if the edit goes wrong.
The 10 GB file is scratch. It is working data. It should not sit on the backed-up disk, and it should not stay after the run.
The result you must keep does not go to the 14-day scratch, and it does not go to home if it is large. It goes to the project space, which lasts for the life of the project. On Snellius a long-term copy can also go to the archive. The next episode names the paths and the lifetimes.
- The metadata server stores names, permissions, and locations. The data servers store bytes.
- A thousand small files mean a thousand metadata operations. One archive means one.
- Home is for the small source file. A 10 GB working file is scratch. A result you must keep is project space.