
Content from Why I/O matters
Last updated on 2026-10-28 | Edit this page
Estimated time: 15 minutes
Overview
Questions
- What is the difference between a metadata server and a data server?
- Why do a thousand small files cost more than one file of the same total size?
- Which of three files belongs on home?
Objectives
- Separate a file’s name and permissions from the bytes of the file.
- Explain why many small files put extra work on the metadata server.
- Choose home for a small source file, and not for a 10 GB working file.
A job does three kinds of work
An HPC application computes, it sends messages between processes, and it reads and writes files. This lesson is the third of those. The other two can be fast and the job can still sit idle, waiting on the file system.
Input is not one thing. A grid, a genome, or a climate field can be a huge file that many processes read. A job parameter file is small. Output is not one thing either. A checkpoint is large and has to be precise, because the next job starts from it. An analysis file can be a subset. A progress log is a short text file from one process.
Those files do not all belong on the same disk. The next episode names the disks. This episode is why the choice changes the runtime.
The metadata server and the data servers
A parallel file system splits the work across two roles.
The metadata server records the name, the owner, the permissions, the size, and the location of the bytes. Creating a file, opening it, listing a directory, and asking for its size all talk to the metadata server. The record for one file is an inode. A quota can count inodes as well as bytes.
The data servers hold the bytes. Once the metadata server has said where a large file lives, the read and the write talk to the data servers.
ls of a directory with a huge number of names is almost
all metadata. Reading one 10 GB file is one metadata lookup and then a
long transfer from the data servers. The second case is what the fast
disks are built for. The first case can leave those disks idle while the
metadata server has a queue of its own.
On Snellius the scratch areas share a GPFS file system. A path that
realpath prints under /gpfs/scratch1/ is that
file system. Home is a different file system: smaller, and backed up.
You will use both. You should not use them for the same kind of
file.
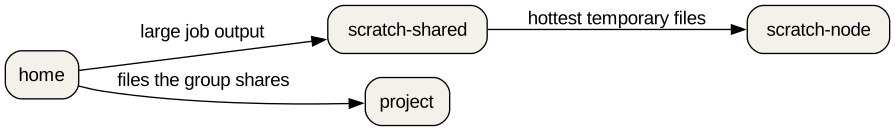
Why many small files hurt
One thousand files of 1 MB hold the same 1 GB as one file of 1 GB. They are not the same amount of work.
Each small file is a create, an open, a write, a close, and a name to store. That is a thousand trips to the metadata server for a modest amount of data. A copy of the directory repeats the work on the destination: a thousand creates, not one.
One archive of those files is one metadata record and one stream of bytes. The copy is then one lookup and one transfer. The data servers do the work. The metadata server does little. Random bytes do not shrink when you compress them. What you save is the number of files, not the number of bytes. A later episode times the copy. The reason is this one.
The same cost shows up in a quota. Home on Snellius has a cap on
inodes as well as a cap on bytes. A tree of tiny files can hit the inode
cap while du still shows free space.
What home is for
Home is the small, backed-up place. A source file you will edit next week belongs there. If you delete it by mistake, the backup can still have it. On Snellius that backup keeps a deleted home file for three weeks.
A 10 GB file that a job is still writing does not belong there. It is large, it is temporary, and putting it through the backup helps no one. A result you must keep until the project ends is a third case. Scratch will expire. Home will fill. The next episode gives that result a project path and, on Snellius, an archive.
Which file belongs on home?
You have three files:
- A source file of a few kilobytes that you will edit next week.
- A 10 GB file a job is writing and will not need after the run.
- A result you must keep until the project ends.
Which one belongs on home? Where do the other two go?
Only the source file belongs on home. It is small, you will change it, and the backup is there if the edit goes wrong.
The 10 GB file is scratch. It is working data. It should not sit on the backed-up disk, and it should not stay after the run.
The result you must keep does not go to the 14-day scratch, and it does not go to home if it is large. It goes to the project space, which lasts for the life of the project. On Snellius a long-term copy can also go to the archive. The next episode names the paths and the lifetimes.
- The metadata server stores names, permissions, and locations. The data servers store bytes.
- A thousand small files mean a thousand metadata operations. One archive means one.
- Home is for the small source file. A 10 GB working file is scratch. A result you must keep is project space.
Content from The file systems
Last updated on 2026-10-28 | Edit this page
Estimated time: 30 minutes
Overview
Questions
- How long does a file last on home, on scratch-shared, in
$TMPDIR, and on the project space? - What does a Snellius quota line say, and what do you run when
myquotais not there?
Objectives
- Match home, scratch-shared, scratch-local, scratch-node, project, and archive to a lifetime.
- Read a 200 GiB home quota and a three-week restore window for deleted home files.
- Use the tab’s paths on the course cluster instead of the Snellius paths.
Six places on Snellius
A path decides the speed, the backup, and the day the file disappears. On Snellius the layout is a table. Learn the table, then read the tab. If your tab does not list a path, that path is not on your machine. Do not create it because the table has the name.
| Place | Speed | Size | Backed up | When it ends |
|---|---|---|---|---|
/home |
Normal | 200 GiB | Yes | Project end, plus 15 weeks |
/scratch-shared |
Fast | 8 TiB, shared with scratch-local | No | 14 days |
/scratch-local |
Fast | Counted in that 8 TiB | No | 6 days |
/scratch-node |
Very fast | The node disk, no quota | No | End of the job |
/projects |
Fast | On demand | No | End of the project |
/archive |
Very slow | On demand | Yes | End of the project |
Home is /home/$USER. The quota is 200 GiB. The file
system is backed up overnight. A home file that has already been backed
up can be restored for three weeks after you delete it. The directory
itself lasts until the project ends, plus 15 weeks. Three weeks is how
long a deleted file stays in the backup. Fifteen weeks after the project
is when the directory itself goes away.
Home is the right place for scripts, configuration, and small inputs. It is a poor place for a multi-gigabyte output. The backup has to copy what you put there, and the quota is the smallest cap in the table.
Scratch is fast temporary space. The default scratch quota is 8 TiB, counted across scratch-local and scratch-shared for your user. There is no backup.
Scratch-shared is /scratch-shared. The login node and
the compute nodes can see it. You make your own directory,
/scratch-shared/$USER. Data that sits unused is removed
after 14 days. Use it for large job output that other nodes, or a later
job this week, must read.
Scratch-local is a directory on that same GPFS scratch, created for a
job and reached as $TMPDIR. The path looks like
/scratch-local/$USER.$SLURM_JOB_ID. realpath
shows a GPFS path under /gpfs/scratch1/nodespecific/. The
directory is specific to the job. A second job on the same node gets a
different directory. The table gives it 6 days. It counts against the 8
TiB quota, so old job directories still count until they expire.
Scratch-node is NVMe on the node itself. $TMPDIR points
at your directory under /scratch-node when the job asked
for it. It is removed when the job ends, so a result you need has to be
copied off before the script exits. There is no quota and no backup. On
Snellius it is not on every node. Fat nodes have it, and a subset of the
rome, genoa, and GPU nodes have it. The
request is --constraint=scratch-node. A shared node gives
you a portion of that disk, not the whole device.
Project space is /projects. It is fast, it is not backed
up, and it lasts until the project ends. This is the place for a result
the group must keep, and for data that is too big for home. The size is
on demand.
Archive is /archive. It is very slow, it is backed up,
and it lasts until the project ends. It is for data you will not read
during the run. The Snellius tab below names it as tape, and as a path
you use from the login and staging nodes.
The course cluster does not have this list
The table is Snellius. The course cluster has a shorter set of paths.
Read them from the tab. Do not type /scratch-shared,
/scratch-node, or /archive unless the tab
lists them.
| Place | Path | What it is for |
|---|---|---|
| Home | /home/$USER |
Shared with the compute nodes |
| Project | /project |
Shared |
| Scratch | /scratch |
Shared with the manager, not a separate parallel scratch |
| Node disk | $TMPDIR |
This job only. Removed when the job ends |
There is no /scratch-shared, no
/scratch-node, and no /archive.
On the course cluster the tab has home, a project path, a scratch
path, and $TMPDIR for the job. There is no
/scratch-shared, no /scratch-node, and no
/archive. $TMPDIR is removed when the job
ends. A file on the login node’s scratch is not the same file as a
compute node’s scratch. The later episode writes job files inside the
job.
Read the quota before you fill it
The command depends on the machine. On Snellius, myquota
prints bytes and inodes for home and for scratch. A home line from the
documentation looks like this:
scur1448@home4|GiB:quota=200.00,limit=210.00,usage=0.0000%|Inodes:quota=1000000,limit=1200000,usage=0.0008%quota is the amount you are given. limit is
a little above that. usage is how full you are. Home is 200
GiB and 1,000,000 inodes. Scratch is 8 TiB across scratch-local and
scratch-shared. Inodes are the metadata count from the previous episode.
A small usage on bytes can still sit next to a full inode
quota if the directory is many tiny files.
On the course cluster there is no myquota.
df -h prints size, used, and free for a mount.
du -sh ~ prints one size for your home.
Type along
Run the command in the tab. Read the home number before you copy a large tree.
There is no myquota here.
A job directory is not a place you keep
$TMPDIR inside a job is space for that job. Copy
anything you must keep to home or to the project path before the script
exits. The login node’s $TMPDIR is a different directory.
Do not prepare a job’s files there and expect the compute node to see
them.
$TMPDIR in a job is
/localscratch/$USER.$SLURM_JOB_ID.0 on the node’s own disk.
The cluster deletes it when the job ends. There is one login node, so
compare the login node’s /tmp with a job’s
$TMPDIR.
Scratch-node is the fast case of the same idea, and only on Snellius. The constraint is how you ask for a node that has the disk. The course cluster tab tells you to drop the constraint.
There is no --constraint=scratch-node.
$TMPDIR is already on the node’s own disk. Drop the
constraint and write to $TMPDIR.
Which file is still there?
A job writes the same run.dat in three places:
- A.
/scratch-shared/$USER/run.daton Snellius - B.
$TMPDIR/run.datin a scratch-node job on Snellius, or the job’s$TMPDIRon the course cluster - C. the project path from your tab, for example
/projects/$USER/run.daton Snellius
Nobody touches the files afterwards. Which copies still exist after the job ends? Which still exist 14 days later? Which still exist when the project ends?
After the job ends, A and C are still there. B is gone. Scratch-node
is removed at the end of the job. On the course cluster the job’s
$TMPDIR is removed at the end of the job as well. The login
node cannot open that path in the afternoon.
Fourteen days later, A is gone. Unused scratch-shared data is removed after 14 days. C is still there. B was already gone.
When the project ends, C ends with the project. A ended at 14 days. B
ended with the job. Home is not one of these three. Home would last
until the project ends plus 15 weeks, and a deleted home file can be
restored for three weeks, but a large run.dat should not
have been put there.
Scratch-local, the $TMPDIR you get without
--constraint=scratch-node on Snellius, has its own
lifetime. The table gives it 6 days, and it is not path B.
- Snellius home is 200 GiB, backed up, with three weeks of deleted files in the backup.
- Scratch-shared lasts about 14 days. Scratch-local lasts about 6 days. Scratch-node ends with the job.
- Project space and the archive last until the project ends. The archive is the slow, backed-up copy.
- The course cluster tab replaces this list. Do not invent
/scratch-sharedthere. -
myquotais the Snellius report.df -handdu -share the tools when it is absent.
Content from Files and directories
Last updated on 2026-10-28 | Edit this page
Estimated time: 35 minutes
Overview
Questions
- How do you see the directory you are in, and how do you make a directory on scratch?
- After
mv, what doeslsshow? - What does
rmdirprint when the directory is not empty?
Objectives
- Run
pwd,mkdir -p,cd, andlsso an empty scratch directory prints nothing. - Create a file, show it with
cat, copy it, and rename it solsshows only the new name. - Remove an empty directory with
rmdir, read the error on a non-empty directory, and remove it after emptying it.
The shell starts in home
Right after SSH, the current directory is your home directory.
pwd prints that path. On Snellius it is
/home/$USER. cd with no argument returns there
from anywhere. ls prints the names in the current
directory. An empty directory prints nothing. That empty print is
success, not an error.
The scratch directory in the first task is not home. On Snellius it
is /scratch-shared/$USER. mkdir -p creates it,
and a second run does not fail if it is already there. The course
cluster has no /scratch-shared. The tab names the scratch
path you do have. Make your directory under that path. The
pwd and ls checks are the same:
ls of a new directory prints nothing.
| Place | Path | What it is for |
|---|---|---|
| Home | /home/$USER |
Shared with the compute nodes |
| Project | /project |
Shared |
| Scratch | /scratch |
Shared with the manager, not a separate parallel scratch |
| Node disk | $TMPDIR |
This job only. Removed when the job ends |
There is no /scratch-shared, no
/scratch-node, and no /archive.
Login node
pwd, mkdir, and cat of one
small file are what the login node is for. Do not generate a thousand
files in this shell, and do not run the print-n program
here. Those belong in the last episode, and they go through
sbatch.
Type along
Use the Snellius commands if your tab lists
/scratch-shared. Otherwise use the scratch path in the tab,
then the same pwd and ls.
Task 1: make a scratch directory and show that it is empty
pwd starts as /home/<your-login>.
mkdir -p creates the directory. On Snellius the path is
/scratch-shared/$USER. On the course cluster it is a
directory under the scratch path in the tab, not under
/scratch-shared.
After cd into that directory, pwd prints
it. ls prints nothing. No names, and no error, means the
directory is empty.
cd with no argument returns to home. pwd
prints /home/<your-login> again.
A file you can show, copy, and rename
touch creates an empty file. An editor such as
nano or vim puts text in it. cat
prints the file. printf is a way to put one known line in
the file without an interactive editor, so the later cat
has an answer you can check.
cp copies. The original stays. mv changes
the name. After mv, ls of that directory shows
the new name and does not show the old name.
Task 2: copy, then rename
Start in home. On Snellius the scratch directory is
/scratch-shared/$USER. On the course cluster, use the
directory you created under the scratch path in the tab. The commands
below say SCRATCH. Set it to that directory before you
copy.
BASH
cd
SCRATCH=/scratch-shared/$USER
printf 'one line\n' > notes.txt
cat notes.txt
mkdir -p "$SCRATCH"
cp notes.txt "$SCRATCH/notes.txt"
ls "$SCRATCH"
mv "$SCRATCH/notes.txt" "$SCRATCH/notes-kept.txt"
ls "$SCRATCH"
ls notes.txt
On the course cluster, set SCRATCH to the directory you
created under the scratch path in the tab. Do not use
/scratch-shared/$USER there.
cat prints:
one lineThe first ls of the scratch directory prints
notes.txt.
The ls after mv prints
notes-kept.txt and does not print notes.txt.
The new name is the only name in that directory.
The last ls notes.txt still finds the original in home.
cp left it there. mv renamed only the
copy.
Directories, empty and not
mkdir creates a directory. cd enters it.
rmdir removes a directory only when it is empty. That limit
is useful. rmdir will not delete a tree of files because
you pointed it at the wrong place.
If the directory still has a file, rmdir prints an error
and leaves the directory in place. Remove the file, then run
rmdir again.
pwd inside demo-dir ends in
/demo-dir. ls there prints nothing.
After cd back to home, rmdir demo-dir
removes it because it is empty. The following ls does not
list demo-dir.
The first rmdir fails. The message is:
rmdir: failed to remove 'demo-dir': Directory not emptydemo-dir is still there, and keep.txt is
still inside it. rmdir did not delete the file.
rm demo-dir/keep.txt empties the directory. The second
rmdir then succeeds. ls in home does not list
demo-dir.
-
pwdprints the current directory. A new shell starts in home. -
mkdir -p /scratch-shared/$USERis the Snellius scratch directory. The course cluster uses the path in the tab. -
lsof an empty directory prints nothing. - After
mv,lsshows the new name only.cpleaves the original. -
rmdirremoves an empty directory. On a non-empty directory it errors, and it succeeds after you empty it.
Content from Permissions and quota
Last updated on 2026-10-28 | Edit this page
Estimated time: 30 minutes
Overview
Questions
- What does
chmod g-rchange in the mode string? - How do you see whether home is close to full?
Objectives
- Read the ten-character mode string from
ls -l. - Remove group read with
chmod g-rand read the new string. - Run the quota command for your machine and name the home cap on Snellius.
The mode string
ls -l prints one line per file. The first field is the
mode string. It has ten characters.
The first character is the type. - is a regular file.
d is a directory.
The next nine characters are three groups of three: the owner, the
group, and everyone else. Each group is r, w,
x, or - when that permission is absent.
r is read, w is write, x is
execute.
- rw- r-- r--with the spaces removed is -rw-r--r--. The owner can
read and write. The group can read. Everyone else can read. Nobody can
execute.
The numbers match the letters. Read is 4, write is 2, execute is 1.
Add them inside one group. rw- is 6. r-- is 4.
chmod 644 sets -rw-r--r--.
chmod 640 sets -rw-r-----: the owner can read
and write, the group can read, and everyone else has nothing.
chmod can also change one letter. The form is who, then
+ or -, then the letter. u is the
owner, g is the group, o is everyone else.
chmod g-r means “group, remove, read”. It does not change
the owner, and it does not change everyone else.
A new file’s starting string depends on the account. On Snellius the
hands-on files in the source notes are -rw-r-----. Your
file may already lack group read. Set a known mode first, then remove
the bit, so the change is visible.
Quota is a cap, not a suggestion
Home on Snellius is 200 GiB, with a limit a little above the quota, and a separate cap on inodes. Scratch is 8 TiB across scratch-local and scratch-shared. A full home stops the next copy. It also stops you writing the script that would move the data.
The command is in the tab. On Snellius it is myquota. On
the course cluster there is no myquota. df -h
prints size, used, and available for each mount you name.
du -sh ~ prints one total for home, not a line per file.
-s is the summary. -h prints units you can
read.
There is no myquota here.
Do not fill home
A multi-gigabyte output does not belong in home. Home is 200 GiB on Snellius and it is backed up. A full quota stops the small edits too. Write large job output to scratch or to the project path, and remove a test file when the exercise is over.
After chmod 640, ls -l shows
-rw-r-----. The type is -. The owner is
rw-. The group is r--. Everyone else is
---.
chmod g-r removes the group’s r. The next
ls -l shows -rw-------. The owner is
unchanged. Everyone else is unchanged.
If your ls -l after chmod 640 is not
-rw-r-----, write down the string you do see.
chmod g-r still only clears group read. The group column
becomes --- when it started as r--.
Task 5: read the quota
Run the command in the tab.
There is no myquota here.
On Snellius, what is the home quota in GiB, and what else does the
line count? On the course cluster, which commands replace
myquota, and what does each print?
On Snellius, myquota prints a home line with
quota=200.00 in GiB. The limit in the documented example is
210.00. usage is the fraction already used.
The same line counts inodes: the documented quota is
1000000. A scratch line is in TiB, with quota
8.00, counted across scratch-local and scratch-shared.
On the course cluster, myquota is not installed.
df -h prints one line per mount you named, with the size,
the amount used, and the amount free. du -sh ~ prints a
single size for your home directory.
A home usage near the quota is the signal to move large
files before the next job, not after the write has failed.
- The mode string is type, then owner, group, and everyone else.
-
chmod 640sets-rw-r-----.chmod g-rthen sets-rw-------. - Snellius home is 200 GiB.
myquotaprints the cap and the inode cap. - Without
myquota,df -hshows the mounts anddu -sh ~shows home.
Content from Space for a job
Last updated on 2026-10-28 | Edit this page
Estimated time: 40 minutes
Overview
Questions
- What does a job’s
$TMPDIRlook like, and why do two jobs on one node get two directories? - How do you ask Snellius for scratch-node, and what do you do on a cluster that has no such disk?
- How do you shrink
ex1/run.shwithout editing it?
Objectives
- Submit a job that lists
$TMPDIR, creates a file there, and printsrealpath. - Read the
tcn386transcript: job4401218and job4401219are two directories on one node. - Request scratch-node on Snellius, and follow the tab where that constraint does not exist.
- Run
print-nfor 10^6 to 10^9 values on Snellius, oriend=8 wdir=TMPDIR sbatch run.shon a small cluster.
The directory belongs to the job
$TMPDIR inside a job is a directory the scheduler
created for that job. It is not the login node’s /tmp, and
it is not the login node’s $TMPDIR. Write scratch files
there. Copy anything you must keep to a path that lasts, before the
script exits.
The tab says what the variable points at on your machine.
$TMPDIR in a job is
/localscratch/$USER.$SLURM_JOB_ID.0 on the node’s own disk.
The cluster deletes it when the job ends. There is one login node, so
compare the login node’s /tmp with a job’s
$TMPDIR.
On Snellius, a compute-node $TMPDIR is
/scratch-local/$USER.$SLURM_JOB_ID. realpath
prints the GPFS path under
/gpfs/scratch1/nodespecific/<node>/. Two jobs on the
same node get two directories. The job id is in the name. On the course
cluster, $TMPDIR is on the node’s own disk and is deleted
when the job ends. There is one login node, so the comparison is the
login node’s /tmp against a job’s $TMPDIR, not
two login nodes.
This script is the check. It prints the node, lists the directory,
creates one empty file, lists again, and prints both the variable and
realpath.
BASH
#!/bin/bash
#SBATCH -J files
#SBATCH -t 5
#SBATCH -p rome

hostname
ls -l $TMPDIR
touch "$TMPDIR/testfile.foo"
ls -l $TMPDIR
echo $TMPDIR
realpath $TMPDIR
-t 5 asks for five minutes. -J files is the
job name. The script’s partition line is -p rome, as
published. Leave that line as it is in the file. Submit the file with
sbatch. Do not run it with bash on the login
node.
The source notes recorded two submits that both ran on
tcn386. The output files were
slurm-4401218.out and slurm-4401219.out.
tcn386.local.snellius.surf.nl
total 0
total 0
-rw-r----- 1 scur1448 scur1448 0 Nov  9 00:25 testfile.foo
/scratch-local/scur1448.4401218
/gpfs/scratch1/nodespecific/tcn386/scur1448.4401218
tcn386.local.snellius.surf.nl
total 0
total 0
-rw-r----- 1 scur1448 scur1448 0 Nov 9 00:25 testfile.foo
/scratch-local/scur1448.4401219
/gpfs/scratch1/nodespecific/tcn386/scur1448.4401219Read it from the top. hostname is the compute node,
tcn386, not a login node. The first ls -l
prints total 0 and no file. The directory was empty. The
second ls -l prints total 0 and then
testfile.foo. touch created an empty file, so
the size is 0. The mode -rw-r----- is the mode from the
previous episode.
echo $TMPDIR prints
/scratch-local/scur1448.<jobid>.
realpath prints
/gpfs/scratch1/nodespecific/tcn386/scur1448.<jobid>.
Those are two names for one directory. The job id changes. The node in
this pair does not: both jobs ran on tcn386.
Scratch-local can still be listed after the job has written the file. It counts against the scratch quota until it expires. The table in the previous episode gives it 6 days. From a Snellius login node the source notes listed leftover directories with:
That printed three directories on tcn386, for jobs
4401213, 4401218, and 4401219.
Your login replaces scur1448. Do not run that
ls on the course cluster. There is no
/gpfs/scratch1/nodespecific there.
Login node
Submit the script. Do not execute it on the login node. A write there
uses the shared login node, and the temporary directory you see is not
the job’s $TMPDIR.
Read the two job outputs
Using only the transcript above: did the two jobs share a node? Did they share a directory? Which printed path is the GPFS path?
They shared a node. Both hostnames are
tcn386.local.snellius.surf.nl.
They did not share a directory. The ids are 4401218 and
4401219. Same node, two job directories.
The GPFS path is the realpath line,
/gpfs/scratch1/nodespecific/tcn386/scur1448.<jobid>.
The /scratch-local/... line is the other name for that same
directory.
The output has six parts:
- A compute-node hostname, not your login node.
-
total 0from the firstls -l, with no filename. -
total 0andtestfile.foofrom the secondls -l. The size is 0 becausetouchcreates an empty file. -
echoprinting$TMPDIR. -
realpathprinting another absolute path for that same directory.
On Snellius the two paths look like
/scratch-local/$USER.<jobid> and
/gpfs/scratch1/nodespecific/<node>/$USER.<jobid>.
A second submit gets a new job id in the name, even on the same
node.
On the course cluster the path is the one in the $TMPDIR
tab, on the node’s disk, and the directory is removed when the job ends.
The output file from sbatch remains in the directory where
you submitted. That file is how you read the path after the job.
Scratch-node ends with the job
Scratch-node is the same idea on a faster disk, and only on Snellius.
The disk is NVMe on the node. $TMPDIR points at your
directory on it. The directory is removed when the job ends. There is no
quota. Copy results off before the script exits. The node feature is not
universal, so the script asks for it.
There is no --constraint=scratch-node.
$TMPDIR is already on the node’s own disk. Drop the
constraint and write to $TMPDIR.
The course cluster has no --constraint=scratch-node.
$TMPDIR is already on the node’s disk. Drop the constraint
and still write to $TMPDIR.
Write one file on the fast disk
On Snellius, submit:
BASH
#!/bin/bash
#SBATCH -J scratch-node-test
#SBATCH -t 5
#SBATCH -p rome
#SBATCH --constraint=scratch-node

touch "$TMPDIR/testfile-scratch-node.foo"
echo "This is a file on scratch-node" > "$TMPDIR/testfile-scratch-node.foo"
realpath "$TMPDIR/testfile-scratch-node.foo"
On the course cluster, follow the tab: do not add
--constraint=scratch-node. Keep the touch, the
echo, and the realpath.
The output is one absolute path, and the path ends in
testfile-scratch-node.foo.
On Snellius that path is on the node disk you requested. The directory is removed when the job ends, so the login node cannot open it afterwards. The line in the slurm output file is the record.
On the course cluster the constraint is absent. realpath
still prints a path ending in testfile-scratch-node.foo,
under the job’s $TMPDIR. That directory is also removed
when the job ends.
If the Snellius job waits and never starts, no node with the feature was free. Read the tab and the script, and do not drop the constraint on Snellius just to get a start. Drop it only on the machine whose tab says to drop it.
A million to a billion values
episodes/files/ex1/print-n.c writes n
random double-precision values to a file, in ASCII or in binary. It then
prints how long the write took, the file size in MB, and the rate in
MB/s. run.sh compiles it and calls it in a loop.
The script loads module load 2025 and
GCC/14.2.0, compiles print-n.c to
print-n.out, and loops i from
ibeg to iend (the end index is excluded). The
defaults are ibeg=6 and iend=10, so
n is 10^6, 10^7, 10^8, and 10^9. The last array is 8 GB of
memory. The file is ASCII, so it is larger than that array.
nmax stops a run that would be even bigger.
wdir is the directory the file is written to. The
default is $HOME. wdir=TMPDIR is a keyword.
The script expands it to the job’s $TMPDIR inside the job.
Setting wdir to the login node’s $TMPDIR
before sbatch would point at the wrong directory. Use the
keyword.
On Snellius, from the ex1 directory:
That is the full run, 10^6 through 10^9 values, into home unless you
set wdir. Remove ex1.dat when you have read
the output. Home is 200 GiB. The file does not belong there
overnight.
On a small cluster, do not submit the full range. The tab has the smaller command. The line for this exercise is:
iend=8 keeps i at 6 and 7, so the job
writes 10^6 values and then 10^7 values, into the job’s
$TMPDIR. iend=8 sbatch run.sh writes those
same two sizes into home, which is the comparison and also the one to
avoid if home is tight. Prefer the wdir=TMPDIR form.
On a two-core node, pass the smaller request on the command line. Do not edit the script.
BASH
sbatch --cpus-per-task=2 pi.sh
sbatch --array=0-99%10 array_job.sh
QCG_MAX_INPUTS=100 sbatch --ntasks=2 qcg_job.sh
iend=8 wdir=TMPDIR sbatch run.sh
Check the core count with sinfo first.
The other lines in that tab belong to later lessons. Use the
run.sh line.
Do not fill home
The published default writes ex1.dat in home. On a small
cluster, iend=8 wdir=TMPDIR keeps the file in the job
directory, which is removed at the end of the job. The slurm output file
in the submit directory is the part you keep. Delete a home copy if you
made one.
Run print-n at the size your machine can hold
The program prints, for each n, a line of this shape,
then the script prints Printing:
1000000 random double-precision values written to <path>/ex1.dat in ascii format
 Elapsed time [s]: <seconds>
 File size [MB]: <size>
 Transfer rate [MB/s]: <rate>
Printing 1000000 elements
The seconds, the size, and the rate depend on the node. ASCII is
about 9 bytes per value (0.123456 and a newline), so the
10^6 file is about 9 MB and the 10^7 file is about 90 MB. Do not expect
those sizes to the last digit. Do expect the size to grow by about ten
times when n grows by ten times.
On Snellius, sbatch run.sh prints four
Printing lines: 1000000, 10000000, 100000000, and
1000000000. The default path is your home directory. Remove
ex1.dat after you have read the rates.
On a small cluster, iend=8 wdir=TMPDIR sbatch run.sh
prints two Printing lines: 1000000 and 10000000. The path
contains the job’s $TMPDIR. That directory is gone when the
job ends. The slurm output file is still in the directory where you
submitted.
This challenge is optional. Skip it when time is short or when
df -h shows little free space. On the course cluster,
create 100 files of 1 MB, not 1000. If home and the scratch path are the
same disk, the copy is not a useful comparison. Use the job’s
$TMPDIR as the destination, or skip the challenge.
Optional: many small files against one archive
This is the cost from the first episode, timed.
On Snellius, create 1000 files of 1 MB in home, then copy them to
scratch-shared. On the course cluster, create 100 files, and use the
scratch path in the tab. Check df -h first. Stop if the
free space is close to the size you are about to write.
| Place | Path | What it is for |
|---|---|---|
| Home | /home/$USER |
Shared with the compute nodes |
| Project | /project |
Shared |
| Scratch | /scratch |
Shared with the manager, not a separate parallel scratch |
| Node disk | $TMPDIR |
This job only. Removed when the job ends |
There is no /scratch-shared, no
/scratch-node, and no /archive.
BASH
mkdir ~/file_transfer_test
cd ~/file_transfer_test
for i in {1..1000}; do
  head -c 1M </dev/urandom > "file_${i}.bin"
done
du -sh ~/file_transfer_test
On the course cluster the loop is {1..100}.
Set DEST to /scratch-shared/$USER on
Snellius, or to the scratch directory from the tab. Do not set
DEST to $TMPDIR in this login shell. The login
node’s $TMPDIR is the wrong disk. On the course cluster, if
you want the node disk, put the cp lines in a job and let
that job expand $TMPDIR.
BASH
time cp -r ~/file_transfer_test "$DEST/"
tar -C ~ -czf ~/file_transfer_test.tar.gz file_transfer_test
du -sh ~/file_transfer_test.tar.gz
time cp ~/file_transfer_test.tar.gz "$DEST/"
Then remove the test, in home and in DEST:
BASH
rm -r ~/file_transfer_test
rm ~/file_transfer_test.tar.gz
rm -r "$DEST/file_transfer_test"
rm "$DEST/file_transfer_test.tar.gz"
Check pwd and echo "$DEST" before
rm -r. Remove only this test.
What do you expect from the two du sizes, and which
time cp finishes sooner?
head -c 1M writes 1,048,576 bytes. A thousand of those
files is about 1000M. du -sh ~/file_transfer_test prints a
size near 1000M or 1.0G. One hundred files,
the course-cluster count, is near 100M.
The archive is about the same size as the directory. The bytes are random. gzip does not compress them. The single file is the win, not a smaller file.
time cp of the archive finishes in less time than
time cp -r of the loose files. The archive is one create
and one stream of bytes. The directory is a thousand creates. That is
the metadata server from the first episode.
After the four rm commands,
ls ~/file_transfer_test fails because the directory is
gone, and ls "$DEST/file_transfer_test.tar.gz" fails for
the same reason. Home is back to the size it had before the test.
-
$TMPDIRin a job is that job’s directory. Two jobs ontcn386gotscur1448.4401218andscur1448.4401219. -
realpathon those jobs printed/gpfs/scratch1/nodespecific/tcn386/plus the same job directory. - Scratch-node is
--constraint=scratch-nodeon Snellius. The course cluster drops the constraint and uses$TMPDIR. -
sbatch run.shwrites 10^6 through 10^9 values. A small cluster usesiend=8 wdir=TMPDIR sbatch run.sh. - A thousand small files copy slower than one archive of the same bytes. Clean the test up.